
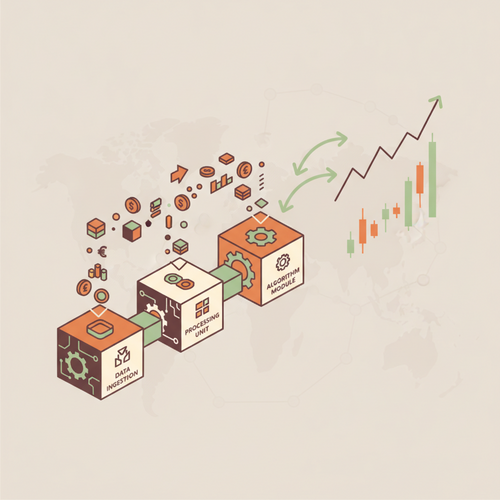
Executive Summary
- Financial Machine Learning Architectures (FMLAs) revolutionize predictive asset pricing.
- Accessible academic modules offer robust frameworks for advanced quantitative analysis.
- Integrating these methodologies enhances alpha generation and sophisticated risk management.
The convergence of financial markets and advanced machine learning represents a paradigm shift. Traditional econometric models often struggle with market non-linearities and high-dimensional datasets. Financial Machine Learning Architectures provide a superior alternative. These sophisticated systems process vast quantities of heterogeneous data. They identify intricate patterns undetectable by conventional methods.
Implementing FMLAs requires deep expertise. However, modular academic components streamline this adoption. These modules encapsulate complex algorithms. They offer researchers and practitioners a solid foundation. Predictive asset pricing becomes more robust and accurate. This translates directly into enhanced investment performance.
Foundational Principles of Financial Machine Learning
Financial Machine Learning (FML) diverges significantly from classical quantitative finance. It emphasizes data-driven model discovery. Unlike prescriptive econometric approaches, FML learns directly from market dynamics. This adaptive capability is crucial in volatile financial environments. FML models prioritize predictive power over strict theoretical assumptions.
Core FML principles include feature engineering and regularization. Feature engineering transforms raw financial data into meaningful inputs. This process requires domain specific knowledge. Regularization techniques prevent model overfitting. Overfitting leads to poor out-of-sample performance. Robust FML models generalize well to unseen market conditions.
Machine learning frameworks process diverse data types. These include traditional market data, alternative datasets, and textual information. Machine learning algorithms identify complex relationships. They capture non-linear dependencies between variables. This capability is paramount for generating consistent alpha. It provides a distinct competitive edge.
Modular Design in Predictive Analytics
Adopting a modular design approach is critical for FMLA scalability. Modular components are self-contained and interchangeable. This structure facilitates rapid development and deployment. It also simplifies model maintenance and updates. Each module performs a specific function within the larger architecture.
Consider a module for volatility forecasting. Another might focus on sentiment analysis. These distinct units can operate independently. They can also integrate seamlessly into a cohesive system. This modularity reduces development friction. It accelerates the iteration cycle for predictive models.
Expert Insight: “From an operational standpoint, modularity ensures that a failure in one component does not cascade throughout the entire system. This isolation capability is invaluable for maintaining system integrity and continuous operation in live trading environments.”
Academic modules often come with rigorous documentation. They frequently include benchmark performance metrics. This transparency is vital for validation. Practitioners can confidently integrate these validated components. They contribute to a more resilient and interpretable predictive framework. Standardization also promotes collaborative research efforts.
Supervised Learning Paradigms for Asset Valuation
Supervised learning forms the bedrock of many predictive asset pricing models. These algorithms learn from labeled datasets. The goal is to predict an output variable based on input features. Regression models forecast continuous values, like future stock prices or volatility. Classification models predict discrete outcomes, such as a stock’s upward or downward movement.
Common supervised learning algorithms include Random Forests and Gradient Boosting Machines (GBMs). Random Forests aggregate predictions from multiple decision trees. This ensemble approach reduces variance and improves accuracy. GBMs sequentially build weak learners. They iteratively correct errors from previous models. Both offer robust performance in complex financial scenarios.
Deep Learning architectures, specifically Recurrent Neural Networks (RNNs) and Transformers, excel in time series analysis. RNNs capture temporal dependencies inherent in financial data. Transformers handle long-range dependencies more efficiently. These models are particularly effective for sequence prediction tasks. They can model complex market microstructure effects.
Feature importance analysis is also crucial. It identifies which inputs drive model predictions. This insight aids in understanding market drivers. It also informs further feature engineering efforts. Regularization techniques like L1 and L2 penalties prevent overfitting. This ensures model stability and generalization. Model validation, including out-of-sample testing, is non-negotiable.
Unsupervised Learning for Market Structure Discovery
Unsupervised learning techniques uncover hidden structures within financial datasets. These algorithms work with unlabeled data. They identify patterns, groups, or anomalies without prior knowledge. This approach is invaluable for portfolio diversification and risk management. It reveals underlying market dynamics.
Clustering algorithms group similar assets together. K-Means or Hierarchical Clustering can identify distinct market segments. This segmentation informs sector allocation strategies. It helps construct diversified portfolios. Principal Component Analysis (PCA) reduces data dimensionality. It extracts the most significant underlying factors. This simplifies complex datasets while retaining critical information.
Anomaly detection algorithms identify unusual market events. These could be fraudulent activities or sudden regime shifts. Autoencoders, a type of neural network, are effective for this. They learn to reconstruct normal data patterns. Deviations indicate anomalous behavior. This capability enhances real-time risk monitoring.
Analyzing correlation structures through unsupervised methods is transformative. It reveals genuine interconnectedness between assets. This moves beyond simple linear correlations. It provides a more nuanced understanding of market dependencies. Such insights are crucial for robust portfolio construction and hedging strategies.
Reinforcement Learning in Algorithmic Trading Strategies
Reinforcement Learning (RL) presents a dynamic approach to algorithmic trading. An RL agent learns through trial and error. It interacts with a simulated or real market environment. The agent receives rewards for desirable actions and penalties for undesirable ones. This feedback loop optimizes long-term trading performance.
RL agents define states, actions, and reward functions. States represent the current market conditions. Actions are trading decisions, such as buying, selling, or holding. The reward function quantifies the profitability or risk of an action. Deep Q-Networks (DQNs) and Actor-Critic methods are prominent RL algorithms used in this domain.
Algorithmic trading strategies developed with RL adapt to evolving market conditions. They do not rely on fixed rules. This adaptability is a significant advantage in volatile markets. RL can optimize complex trading objectives. These include maximizing Sharpe ratio while minimizing drawdown. Backtesting RL agents requires careful consideration of data distribution shifts.
Market Warning: “Deploying Reinforcement Learning in live financial markets demands extreme caution. The ‘explore-exploit’ dilemma can lead to significant losses if not managed judiciously. Robust simulation and rigorous risk controls are non-negotiable.”
The challenge lies in designing effective reward functions. These must align with complex financial goals. Moreover, market non-stationarity poses a continuous hurdle. Continuous learning mechanisms help agents adapt. This ensures ongoing relevance of the trading strategy. RL offers a powerful paradigm for dynamic, intelligent trading systems.
Addressing Data Heterogeneity and Noise in Financial Datasets
Financial datasets are inherently complex. They exhibit significant heterogeneity and pervasive noise. High-frequency data, for instance, presents unique challenges. Issues include irregular timestamps, microstructure effects, and extreme outliers. Effective data preprocessing is paramount for FML model success.
Handling missing data is a critical step. Various imputation techniques exist. These range from simple mean imputation to more sophisticated machine learning-based methods. Proper treatment prevents bias and preserves data integrity. Outlier detection and treatment are equally important. Extreme values can distort model training. Robust statistical methods help mitigate their impact.
Data normalization and standardization ensure consistent scales across features. This is vital for many machine learning algorithms. Time series stationarity is another key concern. Non-stationary data can lead to spurious correlations. Techniques like differencing or fractional differencing transform data into stationary forms. This improves model predictability.
Alternative data sources introduce further complexity. These might include satellite imagery, social media sentiment, or credit card transactions. Integrating these diverse datasets requires careful alignment. Data fusion techniques combine information from multiple sources. This enriches the feature set. It provides a more holistic market view. Ultimately, superior data quality directly translates to superior model performance.
Ethical Considerations and Model Interpretability (XAI)
The increasing sophistication of FMLAs raises critical ethical and interpretability concerns. Black-box models can lack transparency. This opacity hinders accountability. Regulators and investors demand clearer insights. Understanding why a model makes certain predictions is vital.
Explainable AI (XAI) techniques address this challenge. XAI methods provide insights into model decision-making processes. LIME (Local Interpretable Model-agnostic Explanations) and SHAP (SHapley Additive exPlanations) are prominent examples. These tools help practitioners understand feature contributions. They reveal how inputs influence predictions.
Bias detection and mitigation are also paramount. Historical data often contains inherent biases. FML models trained on such data can perpetuate or amplify these biases. This could lead to unfair outcomes or market instability. Regular audits and fairness metrics are essential. They ensure equitable model performance across different groups or conditions.
| XAI Technique | Primary Benefit | Application in FML |
|---|---|---|
| LIME | Local, model-agnostic explanation | Understanding single asset price predictions |
| SHAP | Consistent, global feature importance | Quantifying overall market driver impact |
| Permutation Importance | Feature sensitivity analysis | Identifying critical data inputs for risk models |
Regulatory compliance is another major consideration. Financial institutions must adhere to strict guidelines. Models need to be auditable and reproducible. Academic modules that integrate XAI functionalities offer a significant advantage. They promote responsible AI development in finance. Transparency builds trust with stakeholders.
Implementing Accessible Academic Modules: A Practical Framework
Integrating accessible academic modules into an existing financial infrastructure follows a structured approach. The first step involves identifying specific problem statements. These could range from improving alpha generation to refining risk assessments. Clear objectives guide module selection.
Next, evaluate available academic modules. Consider their documentation, validation status, and community support. Open-source options often provide greater flexibility. They also benefit from peer review. Compatibility with existing data pipelines is a practical concern. Integration should minimize friction and maximize efficiency.
Data preparation is always a critical preceding step. Clean and transform your financial data to meet module input requirements. This ensures optimal performance. Employ robust feature engineering techniques. Align these with the module’s specific needs. Proper data hygiene prevents myriad downstream issues.
Deployment involves rigorous testing in a simulated environment. Backtesting against historical data is essential. Stress testing evaluates module performance under extreme market conditions. This validates its robustness. Monitoring post-deployment is continuous. Performance degradation signals potential issues. This iterative process refines the FMLA over time. It ensures sustained predictive accuracy and operational integrity.
Conclusion
Financial Machine Learning Architectures represent the future of predictive asset pricing. They leverage advanced algorithms to uncover hidden market signals. Accessible academic modules democratize this powerful capability. They provide robust, validated components for complex quantitative tasks. Practitioners can integrate these modules to build sophisticated, high-performance financial models. This enhances investment strategies and improves risk management frameworks. Are you prepared to integrate these cutting-edge methodologies into your quantitative workflow?